Text classification · 2026
Craft Forum Discourse Classification
Can a small labeled dataset support reliable discourse classification—and does DistilBERT actually help?
Text classification · 2026
Can a small labeled dataset support reliable discourse classification—and does DistilBERT actually help?
The dataset contained four kinds of conversation from art and craft forums. Because posts in the same thread share language and context, a random row-level split could make performance look better than it really was.
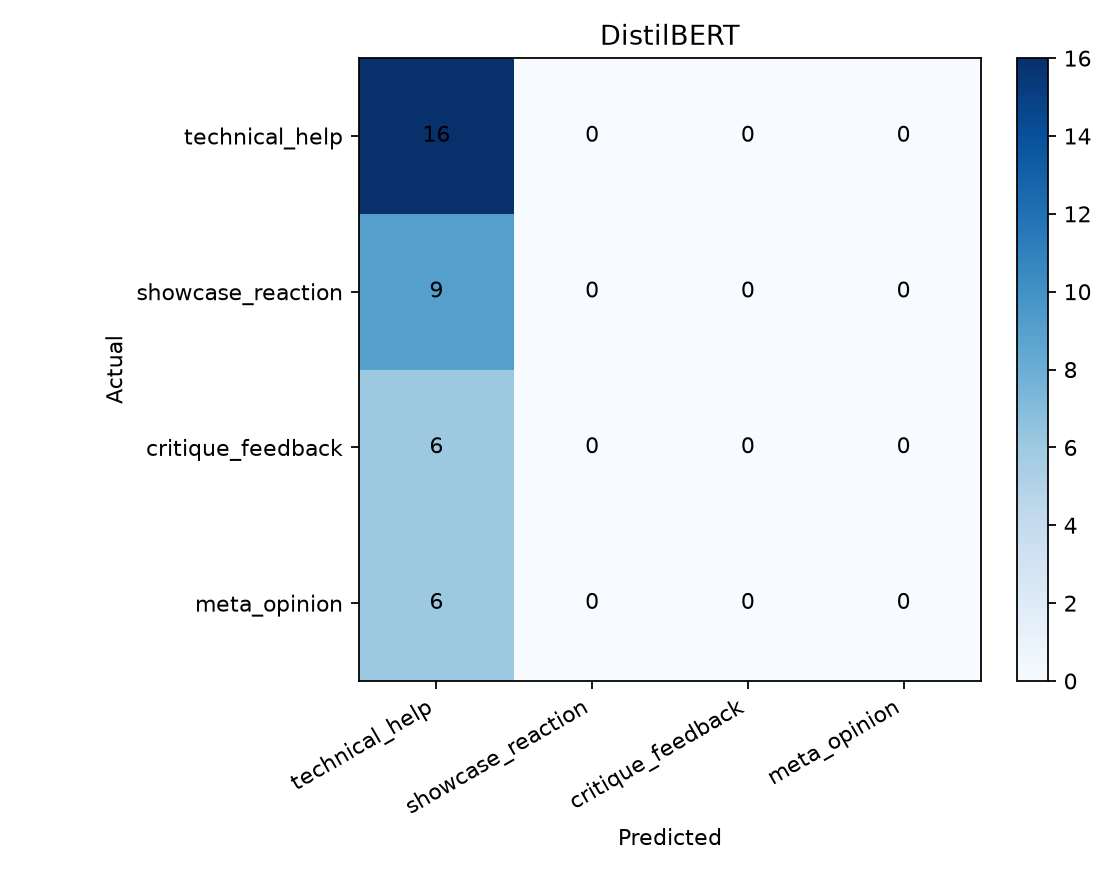
TF-IDF with logistic regression led the four-category comparison. Unweighted DistilBERT predicted the same category for every test post; class weighting raised macro F1 only from 0.151 to 0.172.
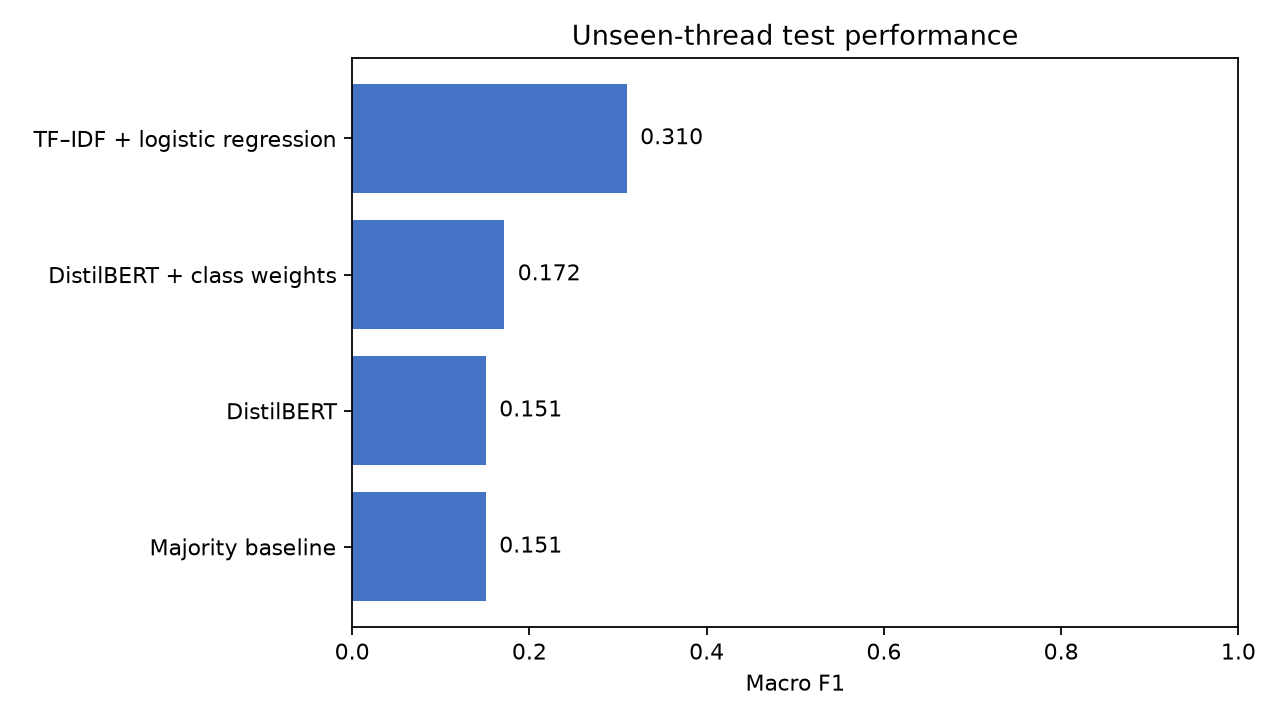
On this dataset, TF-IDF with logistic regression was both stronger and easier to interpret. Keeping whole threads together also kept shared conversational context out of the test set.